Context MCP reference
The reference for Context MCP: endpoints, configuration fields, and text search.
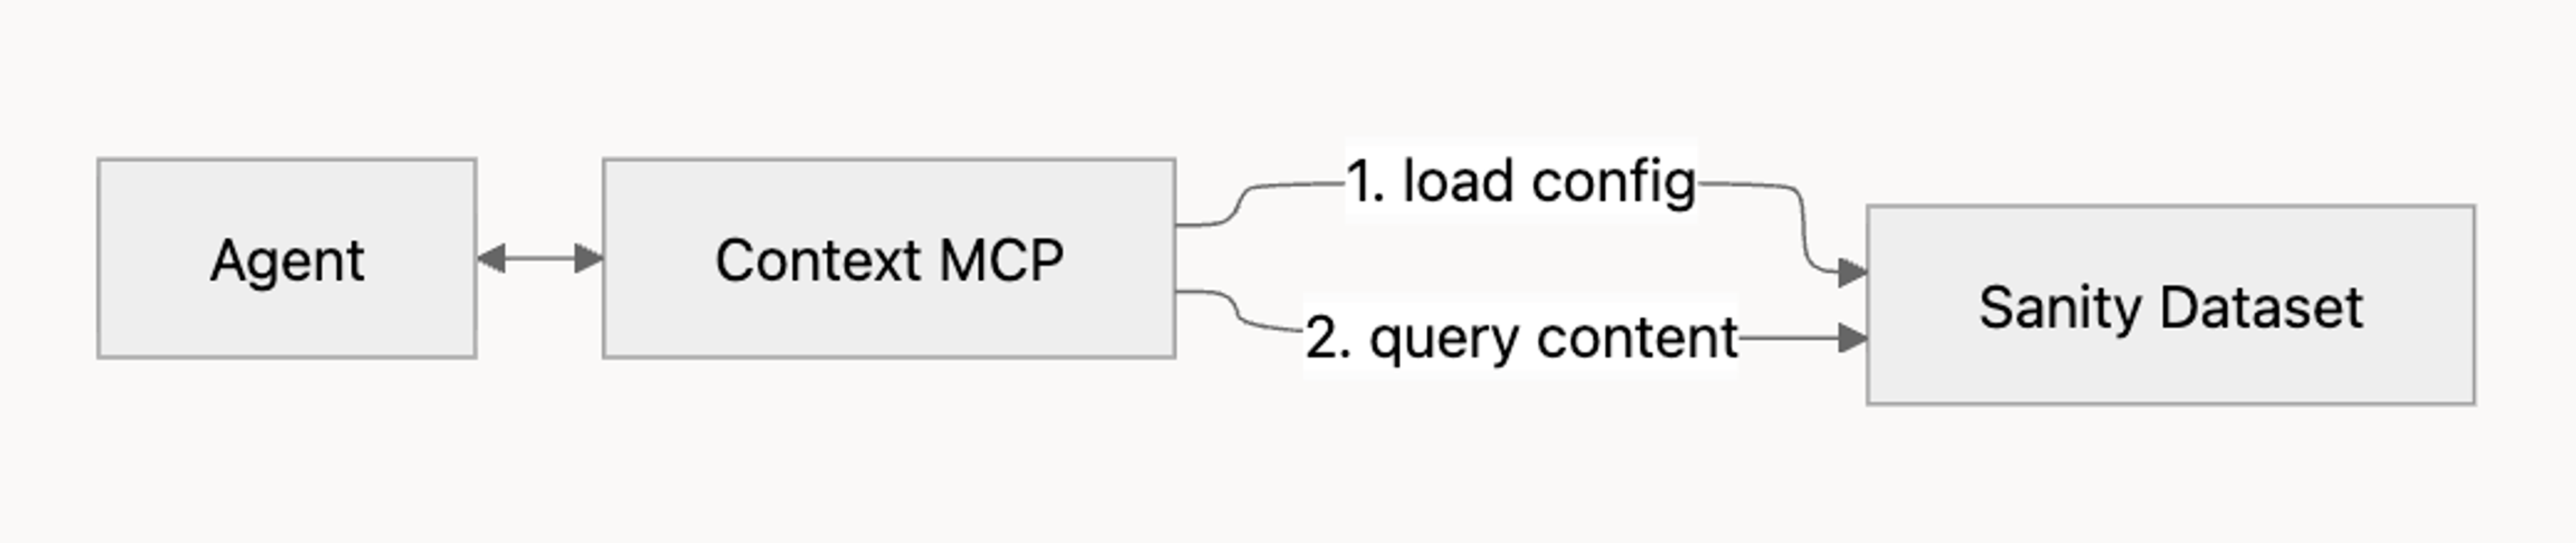
Context MCP is the hosted Model Context Protocol server behind Sanity Context. It gives agents structured, read-only access to your content: from a dataset source, the schema and the documents your configuration allows; from Knowledge Base sources, the Knowledge Bases you choose to serve. It doesn't run the agent loop itself, and it can't write back to your dataset; see Mutations. To connect your first agent, start with Sanity Context.
MCP endpoint configuration fields
An MCP endpoint defines what an agent can access and the instructions it receives. You create and manage MCP endpoints in the Context app in the Dashboard, or with the sanity context mcp CLI commands, so a coding agent can set one up and change it without anyone opening the app; see Configure a Context MCP endpoint for the procedure. Each MCP endpoint has the following fields:
- title. Required. A short, human-readable title for the endpoint, up to 100 characters. Shown only in the Context app, and freely editable.
- name. Required. The identifier the endpoint URL uses. Lowercase letters, numbers, and single hyphens only, up to 64 characters, unique within your organization, and immutable after creation. Set it to something short and stable, like
support-bot. Two shapes are reserved and rejected:by-name, and any name of the formmcpplus eight characters. - sources. Required. What the endpoint serves: up to 100 entries. An endpoint with no sources can't serve agents until you add one. A Knowledge Base source is
{"type": "knowledge-base", "id": "KNOWLEDGE_BASE_ID"}, whereKNOWLEDGE_BASE_IDis the Knowledge Base's public id. Public ids begin withkband are not derived from anything else. A dataset source is{"type": "dataset", "id": "PROJECT_ID.DATASET_NAME"}. An endpoint can have any number of Knowledge Base sources and at most one dataset source, and serves all of them together. - workspace, perspective, semanticSearch. Optional settings on a dataset source.
workspacepicks the Studio workspace whose schema agents use; without it, the first workspace is used.perspectiveispublished(the default),drafts, orraw.semanticSearchis on by default and uses semantic search while the dataset's embeddings are ready; set it tofalseto turn it off. In the Context app, these are the Workspace, Perspective, and Semantic search settings on the dataset source; with the CLI, they're the--workspace,--perspective, and--semantic-searchflags. - instructions. Optional. Custom instructions for the agent, in plain language, up to 10,000 characters. For example: "Only answer questions about product documentation; for anything else, suggest contacting support."
- groqFilter. Optional. A GROQ filter expression, up to 10,000 characters, that limits which documents the agent's queries select. It scopes dataset sources only. See Filtering content.
There is no mode field and no knowledgeBases field. What an endpoint serves is derived from its sources. To serve different sources to different agents, create one endpoint per set of sources.
Filtering content
The groqFilter field accepts a GROQ filter expression, the part inside the [ ... ] of a full GROQ query. It restricts which documents the agent's queries select from your dataset. It applies to dataset sources only; with Knowledge Base sources, the agent can read everything in the Knowledge Bases the MCP endpoint serves. The filter is added to every *[...] selection in the agent's queries, but not to references followed with ->. Documents reached with -> from documents the filter allows, directly or through other referenced documents, stay readable, even if the filter excludes them.
Commonly used operators and functions:
| Operator or function | Use |
|---|---|
| ==, != | Equality |
| >, <, >=, <= | Comparison |
| &&, || | Boolean combination |
| in | Membership |
| defined() | Field existence check |
| match | Text matching, with * as a wildcard |
| references() | Reference to a given document |
| count() | Array length |
| pt::text() | Portable Text as plain text |
There is no operator allowlist. groqFilter accepts anything that parses as a GROQ filter expression, including sub-queries such as _id in *[_type == "category"]._id. A value that starts with *, a bare slice such as [0...10], and a bare pipe function such as order(title asc) are rejected. Pass a predicate, not a projection: an object such as { name, price } passes validation and then matches no documents, so the agent sees an empty dataset. Use it to scope, not to shape; the agent applies its own queries on top of whatever filter you set.
A filter that fails to parse is rejected when you save the MCP endpoint, with 422 Unprocessable Entity, code invalidGroqFilter, and the parser message in the response body.
// Only products
_type == "product"

// Articles and authors
_type in ["article", "author"]

// Only products marked public
_type == "product" && public == true

// Articles whose title starts with "Summer"
_type == "article" && title match "Summer*"
Authentication
Every request carries a bearer token in the Authorization header. An MCP endpoint needs an organization API token with Context Viewer permissions, created in Manage under API > Tokens at the organization level. Viewer is the least privilege that works; Editor also works. For custom roles, the grant behind Context Viewer is sanity.knowledge-base.read.
A project API token is not accepted, however broad its project permissions. Refused requests return these errors:
| Request | Status | MCP connection | /initial-context route | Message |
|---|---|---|---|---|
| No token | 401 | -32001 | missingCredential | "Missing Sanity session" |
| Valid project token from the same organization, endpoint with a dataset source | 403 Forbidden | -32007 | contextGrantRequired | "Serving a dataset requires an organization API token with Context access ('sanity.knowledge-base.read'). Create one under your organization's API settings in Manage." |
| Valid project token from the same organization, endpoint with only Knowledge Base sources | 403 Forbidden | -32006 | knowledgeBaseAccessDenied | "No access to knowledge base '<knowledge base ID>'. Requires one of: sanity.knowledge-base.read." |
<knowledge base ID> is a placeholder for the Knowledge Base's ID.
An invalid or expired token is refused with 401 and the error Session not found (SIO-401-ANF), with no JSON-RPC error code.
MCP endpoint
Once you save an MCP endpoint, the server is reachable at:
https://api.sanity.io/v2026-11-03/context/organizations/:organizationId/mcp/:mcpEndpointName| Segment | Description |
|---|---|
| :organizationId | Your organization ID |
| :mcpEndpointName | Name of the MCP endpoint. Immutable after creation |
An MCP endpoint with a dataset source also needs a Studio (v5.1.0 or later) deployed for that project and dataset. Deploy it with npx sanity@latest deploy. Without one the connection is refused with JSON-RPC error -32004: Only datasets with deployed Studio applications are supported. Please deploy a Studio (v5.1.0+) for this project/dataset.
An endpoint that serves Knowledge Bases but has none it can read is refused outright rather than serving an empty tool list, with JSON-RPC error -32005: No knowledge bases to serve: the endpoint has none, or none of them could be found.
The endpoint serves its configuration only: set everything on the endpoint, not in the URL. A request that adds a query parameter such as groqFilter or perspective is refused with 400 (JSON-RPC error -32602 on the MCP connection) and a message naming the parameter: `groqFilter` is no longer a query parameter. Configure it on the MCP endpoint instead.
For the tools each source type serves, see Context MCP tools.
Text search
This section covers dataset sources. With Knowledge Base sources, agents find entries through the outline and knowledge_base_search, a keyword search over entry content. See Context MCP tools. On top of Content Lake, Context MCP supports keyword text search ranked with BM25, semantic search over dataset embeddings, and a hybrid of the two with selectable boosting. Keyword search matches exact tokens: there is no fuzzy matching and no stemming, so a misspelling returns nothing. Use prefix* to match variants.
Semantic search is available when embeddings are enabled on the dataset and have finished indexing (status: ready), and when the project has AI usage credits remaining. Both checks fail soft: the connection succeeds without semantic search rather than erroring. Semantic search works through the text::semanticSimilarity() GROQ function. The function is only valid as an argument to score(); used anywhere else it returns an error. The agent calls it inside a groq_query. To enable embeddings on the dataset, see Dataset Embeddings.
Semantic search is on by default
Context MCP reads the dataset's embeddings setting itself, so nothing needs enabling on the endpoint and no grant on your token affects detection. To turn semantic search off for an endpoint, set semanticSearch to false on its dataset source, or switch off Semantic search in the Context app.
For when semantic search is worth enabling, see Context MCP source types.
Mutations
Context MCP cannot write to your dataset. If you need an agent that creates or updates documents, run those mutations server-side in your own code after the agent decides what to do. For an MCP-based write path, see the Sanity MCP server.
Next steps
- Context MCP tools. Every tool the endpoint serves, by source type.
- Content access and security. What an agent can reach, and how to bound it.
- Sanity Context patterns and best practices. Scoping, routing, and instructing agents once the basics work.