Sanity Context
Sanity Context gives your AI agents access to content in Sanity, on websites, or in files, so they can provide answers based on your material.
Sanity Context turns your content into knowledge your AI agents can read over the Model Context Protocol (MCP), wherever that content lives: a Sanity dataset, a website you don't manage in Sanity, or a set of files. Agents can query structured content directly with GROQ, or read from a Knowledge Base that Context builds ahead of time.
With Sanity Context, you can:
- Answer customer questions from your own content. Ground a support agent in your help center, product pages, and spec sheets. When the help center says returns are accepted within 30 days and a product page says 45, the build flags the conflict so you can choose the answer once.
- Answer technical questions without version drift. Build a docs agent from your documentation site, release notes, and migration guides, and catch the page that says a feature needs version 4.6 when another says 4.8 before a developer hits it.
- Recommend from your catalog. Give a shopping assistant schema-aware access to products, so a request like a red jacket under $200 becomes an exact filter on real fields instead of a guess.
- Give internal teams one place to ask. Bring together policies, playbooks, security whitepapers, and the deck that never made it online, so people and internal tools stop waiting on a subject-matter expert for answers that are already written down.
- Find where your content disagrees with itself. Every build raises an issue when your sources disagree and nothing says which is right, so a Knowledge Base is useful for cleaning up content drift even before you ship an agent.
What Sanity Context provides, and what you bring
Sanity hosts Context MCP, the server your agent connects to. You bring:
- An MCP-capable AI harness. Your own application built with any framework or SDK that supports MCP. For framework-specific setup, see the connect guides for Claude Agent SDK, Google ADK, LangChain, Mastra, OpenAI Agents SDK, Vercel AI SDK, and Vercel eve.
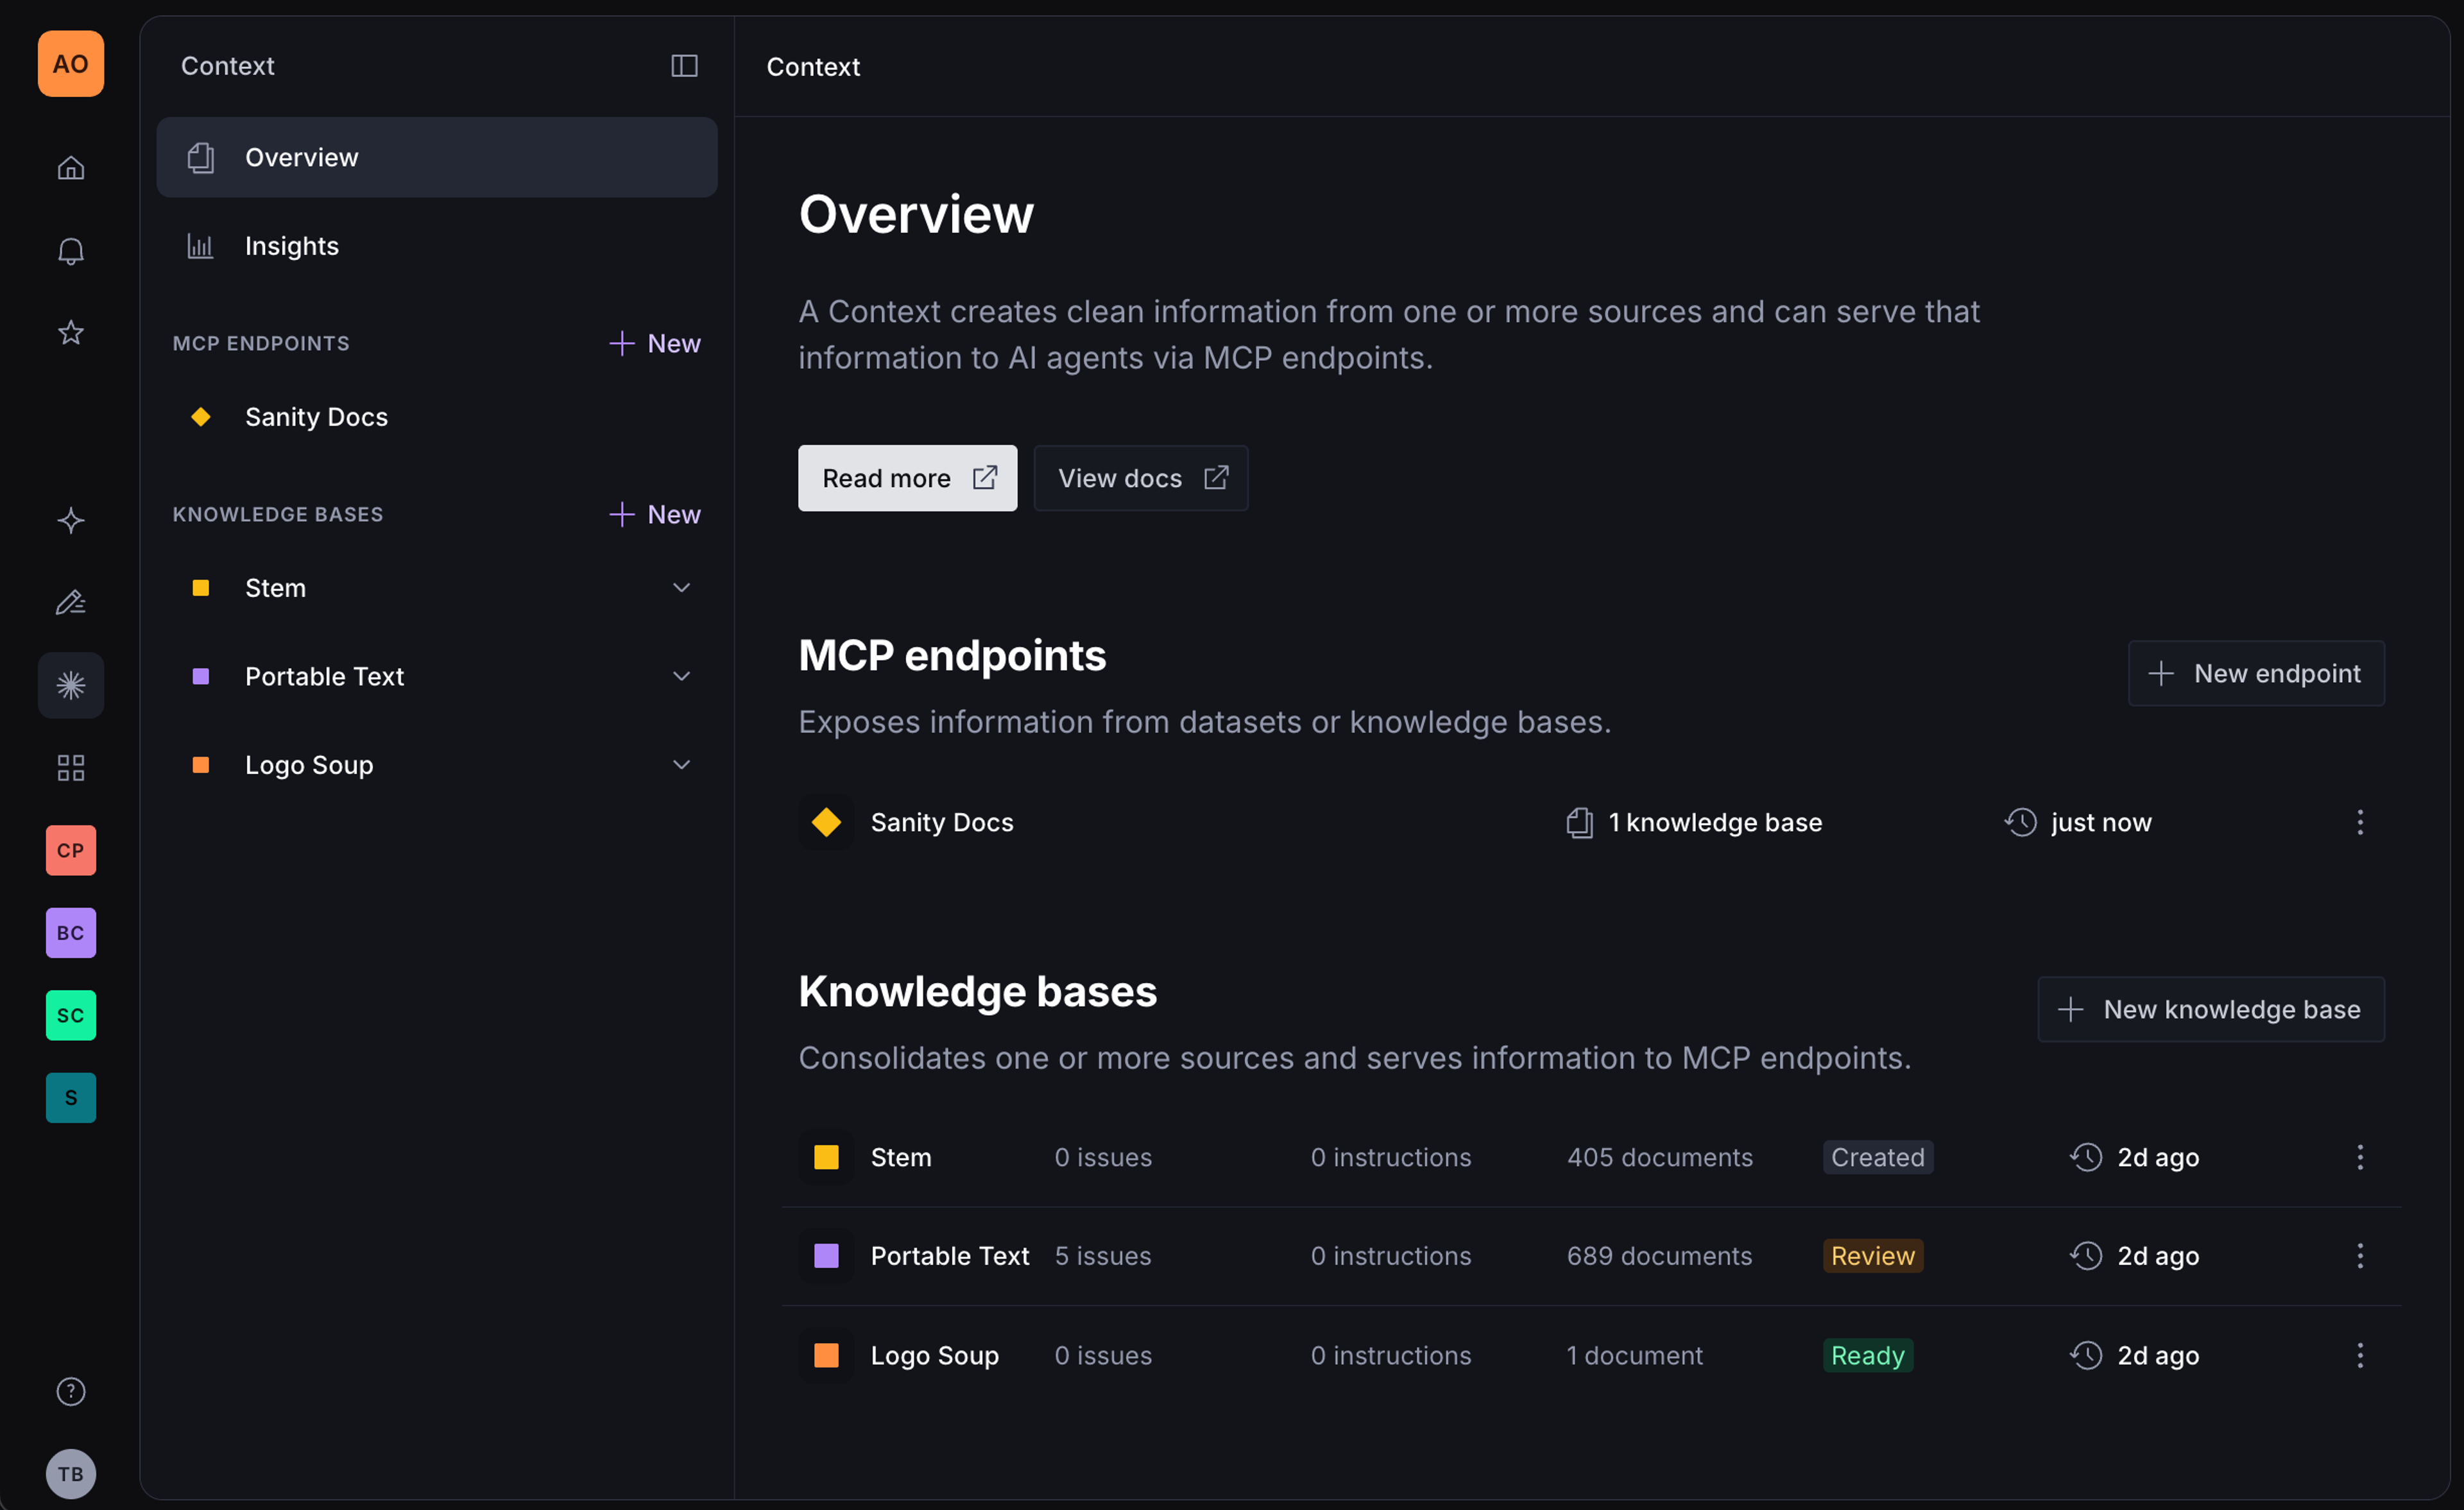
- An MCP endpoint, created in the Context app in the Sanity Dashboard. The configuration that defines what the agent can access, plus optional instructions that shape how it behaves.
Sanity Context provides the knowledge layer: a scoped, read-only window into your content and Knowledge Bases that any agent, copilot, or pipeline can use. It does not run the agent loop itself, and it cannot write back to your dataset.
Looking for a tool to write to your Sanity content?
If you need tools for an agent that creates or modifies content, see the Sanity MCP server, which is a separate server, not a write mode of this one. If you want an editorial assistant with its own harness that runs in the Dashboard, on Slack, or through an API, see Content Agent.
Requirements
To set up Sanity Context, you'll need:
- A Sanity organization with access to Context, and the Administrator or Developer role in it. Creating MCP endpoints requires one of these roles.
- An organization API token with Context Viewer permissions. Create it in Manage under API > Tokens at the organization level, and keep it server-side. Viewer is the least privilege that works for an agent that only reads. Choose Editor if the agent also records conversations in Insights.
- A model and API key. Simple schemas and questions work with small, fast models. If the agent picks the wrong tool or writes malformed GROQ, move to a more capable model.
- Optionally, a frontend application to host the agent. Next.js, for example.
Dataset sources additionally require:
- A Sanity project with content.
- A deployed Sanity Studio 5.1.0 or later for the project and dataset. Deploy it with
npx sanity@latest deploy. - An Administrator or Developer role on the project and unrestricted read access to the dataset, to attach the dataset as a source on an MCP endpoint.
Knowledge Base sources require at least one Knowledge Base that your token can read.
Core concepts
Source types
Context MCP serves content from two source types. A dataset source queries your dataset at request time and suits structured, consistent content, such as product data where exact filters on price or size matter. A Knowledge Base source serves an index built ahead of time and suits facts spread across many documents, sites, and files, where finding the answer is the hard part. Because the reconciling happens during the build rather than while a user waits, the agent can go straight to the right entry, and smaller, faster models can answer accurately. A Knowledge Base can itself be built from datasets, websites, and files; a dataset used that way feeds the build and is not a dataset source on the MCP. An MCP endpoint's sources determine which tools it serves. An MCP endpoint with both a dataset source and Knowledge Base sources serves both sets of tools. See Context MCP source types.
MCP endpoints
An MCP endpoint is the configuration an agent connects to: what content it can reach, and any instructions that shape its behavior. You create and manage MCP endpoints in the Context app, so you can change what an endpoint serves without redeploying the agent. See Configure a Context MCP endpoint.
Initial context
At the start of a conversation the agent orients itself through initial context, which depends on the endpoint's sources: a compressed schema overview for a dataset source, the Knowledge Base outline for Knowledge Base sources, or both when the endpoint has both. If you control the system prompt, you can fetch the initial context over HTTP and skip the initial_context tool call. See Inline initial context into your system prompt.
Knowledge Bases
A Knowledge Base is an index that Context builds ahead of time from the sources you choose: Sanity datasets, websites, and uploaded files. A build organizes the material into topic entries, cites each entry back to its sources, and raises an issue when sources disagree and nothing says which is right, so you decide the answer once instead of leaving the agent to reconcile it on every question. Agents find answers by navigating the Knowledge Base's outline and searching entries by keyword, not by embedding search. See Knowledge Bases and Knowledge Base source types. Once a Knowledge Base is live, you keep it current and resolve the issues a build raises.
Content access
Access is decided when the agent connects: your organization token authorizes the connection, the MCP endpoint's sources decide what it serves, and a GROQ filter scopes dataset reads. Context MCP is read-only for both source types. See Content access and security.
Limitations
- Context MCP is read-only. It cannot create or update documents.
- It does not run the agent loop. You bring the harness and the model.
- Knowledge Bases don't connect directly to tools such as Google Drive, Notion, or Confluence. Export the content and upload it as files.
- Your organization's plan sets how many Knowledge Bases it can have and how many source chunks they can hold. See Context plans and limits.
Next steps
- Quick start: connect an agent to Sanity Context. Serve a dataset from an MCP endpoint and ask it a question.
- Context MCP reference. The reference for endpoints and configuration.
- Context MCP tools. Which tools an endpoint serves for each source type, and what each one does.
- Sanity Context patterns and best practices. Scoping, routing, and instructing agents once the basics work.
- Quick start: build a Knowledge Base and ask it a question. Build one from a website or files and ask it a question.